AI news · October 15, 2026
Researchers report high bypass rates against image safety filters
Image safety needs continuous adversarial evaluation: a low average bypass rate can still leave a repeatable failure path in a public product.
- reported DALL-E 3 bypass
- 13%
- reported Nano Banana 2 bypass
- <10%
- reported GPT-Image-2 bypass
- ~3%
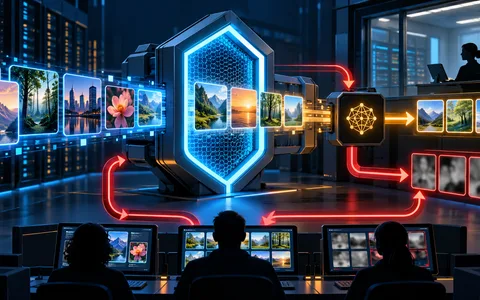
Ars Technica reported on October 14 on a White Circle preprint that evaluates image generators with an iterative red-team method called RISE. The report says the evaluator used an unaligned language model to generate attack attempts and a separate model to judge outputs, producing reported bypass rates of about 13% for DALL-E 3, below 10% for Nano Banana 2 and about 3% for GPT-Image-2. The researchers propose releasing the evaluation pipeline.
The safe builder lesson is process, not reproduction of harmful prompts. Test policy boundaries with an approved internal suite, keep the judge and generator separate, log model and policy versions and review borderline outputs. Add rate limits, abuse reporting and human escalation around image generation. The reported rates come from one research setup and should not be treated as a universal ranking; repeat the evaluation on the exact model and release that you operate.
What you can do with it
Create a closed safety test set with benign labels, policy categories and expected outcomes. Run it on every model update, sample borderline outputs for human review and block release when the bypass rate or severity crosses your chosen limit. Keep harmful test content access-controlled.
Our take
The strongest point is operational: safety is a regression test, not a launch checkbox. Reported attack rates can move with prompts, judges and model versions, so the useful asset is a repeatable internal harness with a clear stop rule.
Source: Ars Technica / White Circle — Made With Models writes the brief; the reporting is theirs.