News archive
October 11, 2026
Satya Nadella says AI agents need an emergency brake and external controls
Microsoft's Satya Nadella says model controls should sit outside the model, with logs and a human able to pause or shut down an agent; builders should design this before adding autonomy.
1 external shutdown path called for
Apple hires some Huxe staff and licenses its podcast AI technology
Apple's Huxe deal is an employee offer plus a non-exclusive IP license, not an acquisition; builders should watch for product access before treating a talent deal as a new platform.
Microsoft Execution Containers put AI agent access behind runtime policies
Microsoft's MXC 1.0 lets developers declare files, network, UI, and process rules outside an agent; its early-preview repo warns policies can be overly permissive, so test the exact backend before trusting it.
TypeSafe's decision model Jev is valued at $7.5B weeks after launch
TechCrunch reports TypeSafe raised $870M at a $7.5B valuation after Jev's September launch; Jev returns typed probabilities, not prose, so test it on routing tasks instead of treating it as a chat replacement.
$870M reported funding$7.5B reported valuation70-500ms vendor-reported response time
Danu's recycling robot uses computer vision to pick materials from mixed waste
Danu says its H.E.R.O. robot can add an estimated $485K in revenue per site against $160K capex; builders should demand site-level pick and maintenance data before trusting the model.
$485K estimated added revenue per site$160K estimated capital cost$24K estimated annual maintenance
AGILINK robot hand threads 16-strand silk in an embroidery demo
AGILINK's OmniHand 3 Ultra demo splits silk into 16 strands and uses 21 active degrees of freedom; the useful robotics test is repeatable force control, not a single viral clip.
16 silk strands in the demo21 active degrees of freedom
Ukraine strikes two Yandex data centers used for AI services
Ars reports strikes damaged two of Yandex's five data centers, including two of its three YandexGPT training supercomputers; AI products need a capacity and failover plan, not only a model plan.
2 of 5 Yandex data centers affected2 of 3 YandexGPT training supercomputers at one site
Nikon disqualifies a microscopy video over generative AI rules
Nikon replaced a contest winner after finding the entry broke its generative-AI rule; creator tools need explicit AI-use declarations, review evidence, and an appeal process when authenticity affects payment or ranking.
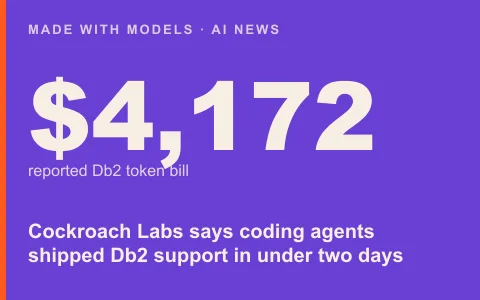
Cockroach Labs says coding agents shipped Db2 support in under two days
Cockroach Labs reports a hospital-style agent workflow delivered Db2 support in under two days for $4,172 in tokens, with 55 review send-backs; structured review, not raw code volume, made the case.
$4,172 reported Db2 token billunder 2 days reported Db2 delivery time55 review send-backs
Talorys packages a personal AI agent into your Cloudflare account
Talorys installs with npx create-talorys@latest and keeps chat, memory, tasks, and reminders in one Cloudflare account; it is cloud-managed, not local, so check vendor and usage limits first.
REA gives coding agents tools to reverse-engineer installed software
REA adds a reverse-engineering workflow to a coding agent with npx rea-agents@latest setup; its examples inspect Calculator and the Chrome Dino game, so start with software you own and a reviewable test case.
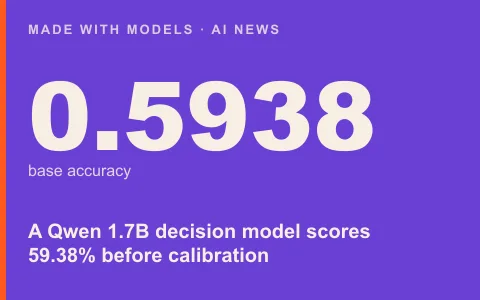
A Qwen 1.7B decision model scores 59.38% before calibration
Nish Tahir constrains Qwen3-1.7B to five choices, gets 59.38% on a 1,221-item CommonsenseQA sample, then shows 0.9978 confidence on an ambiguous answer; calibrated scores need testing.
0.5938 base accuracy0.6241 quick fine-tune accuracy3.797 temperature scaling value
Saluki compresses Qwen3.8-27B into a 7.89GB tool-calling model
The Saluki model card lists a 7.89GB Qwen3.8 quant with 88/120 tool-call passes versus 84 for the full model, but also reports weaker math and formatting; test your own agent loop.
7.89GB listed GGUF file size88/120 reported tool-call score30 vs 33 reported SWE-bench Verified score
A terrorism-safety benchmark finds open model safeguards can be stripped
Tech Against Terrorism's test reported three in five models failing a terrorism-safety benchmark and Llama 3.1 8B dropping from 97 to about 3 after abliteration; treat exact model files as a supply-chain input.
>130 models tested3 in 5 reported benchmark failures97 to about 3 reported Llama 3.1 8B score change
Revolut plans agentic shopping inside its AIR assistant
Sifted reports Revolut plans to add shopping actions to AIR, its in-app financial assistant; builders should specify approvals, spend caps, merchant identity, and audit logs before an agent can buy.