AI news · October 8, 2026
EmbeddingGemma 2 puts multimodal search inside a phone-sized model
EmbeddingGemma 2 can run with about 191MB of active RAM for text-only use and 567MB for full multimodal use. It targets local search and intent routing without fine-tuning.
- parameters
- 740M
- text-only active RAM on Pixel 11 Pro
- 191MB
- full multimodal active RAM
- 567MB
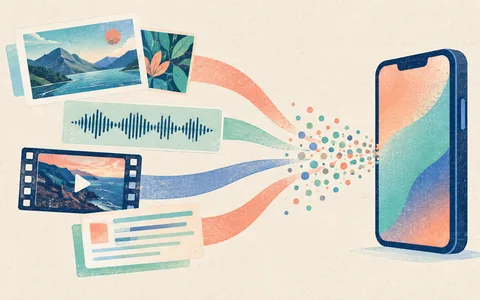
Google released EmbeddingGemma 2 on October 6 as an open-weight multimodal embedding model. It maps text, images, video, and audio into one vector space, so a local search system can compare a spoken clip, a photo, and a text query without sending each item to a remote service. Google reports about 191MB of active RAM for text-only use and about 567MB for full multimodal use on a Pixel 11 Pro. The model has 740 million parameters and supports 768-dimensional embeddings.
The first useful products are narrow local search tools rather than general assistants. Google shows an Instant Media Search demo and a Video Moments Finder, while the AI Edge Gallery and Foresight on Mac are available for testing. Android ML Kit support is planned in the coming weeks. Builders should test recall on their own media and check battery cost, indexing time, and privacy needs before calling a local embedding model ready for a full library.
What you can do with it
Try EmbeddingGemma 2 through Google AI Edge Gallery. Build a small mixed set of photos, clips, audio, and notes, then score the top results for ten real queries. Compare local latency, RAM use, battery impact, and search recall with the embedding service you use today.
Our take
This is a practical release because multimodal search is often more valuable on a device than in a chat window. The memory figures make small local indexes plausible. The missing proof is real-world recall across messy personal media, where labels and sound quality are uneven.
Links Try today Release Model card
Source: Google ↗ — Made With Models writes the brief; the reporting is theirs.